Make technical checks reproducible

Technical SEO Checklist

Technical SEO helps search engines fetch your pages, read their content and identify which URLs belong in search. Use this checklist to remove accidental crawl blocks, repair broken routes, set canonical URLs and improve the experience of real visitors. Each task explains where to look and what to change, with examples you can adapt to your site.

Free to useNo account neededSaved in your browser
Connected page tiles and a magnifying glass leading toward a highlighted preferred page.
An editorial illustration
Your working checklist

Work through the checklist

Click a square to mark a task as Pass. Click again to undo. Use the result menu for a problem, a blocker or a task that does not apply. You do not need to enter notes.

21 checks

Fix Crawl Blocks, HTTP Errors and Redirects

Crawling fetches a URL. Remove accidental robots blocks, return correct HTTP responses and redirect moved pages. A valid 404 on deleted content differs from a broken live page.

Fix HTTP errors on pages that should be live

Find the response code that tells you whether a page request succeeded.

Use this for: Public pages expected to be live.

HTTP response codes describe the server’s answer. A normal public HTML page should return 200 and its actual content. A 403 refuses access, a 404 means not found, and 5xx indicates a server-side problem.

In Chrome Developer Tools → Network, reload and select the main document. Read Headers → Status Code. Restore a live page’s missing route or correct the link. Give the host the address and time of a 5xx error to investigate.

Example

Illustrative example: /services/boiler-repair/ appears in the menu but returns 404. Restore the page or correct the menu destination.

  1. Open the public page with Network recording.
  2. Check the document’s status and displayed content.
  3. Repair the route, access rule or server fault, then reload.
More help and optional notesCritical · Developer
PassThe intended live page returns a successful response and its expected content.
FailThe route returns an error, unintended login, empty page or error message with a success response.

If it fails: Restore the route or correct access/server errors.

Retest: Reload and inspect the response.

Not applicable: Pages outside this public scope.

Keep in mind: A successful response does not guarantee indexing.

Optional: useful finding. Keep confidential data out of shared exports.

No result recorded yet.

Changing this result updates your checkmark and progress immediately. Notes are optional.

Remove accidental robots.txt crawl blocks

Check that robots.txt does not accidentally block important pages or resources.

Use this for: Production crawl rules.

Robots.txt controls which paths compliant crawlers may fetch. Open /robots.txt using the page’s protocol and host. Find the applicable User-agent group and read both Allow and Disallow rules, including more specific path exceptions.

Check important page paths and required CSS or JavaScript files. In the CMS robots.txt setting, or with a developer, remove or narrow accidental blocks while preserving deliberate restrictions. This does not remove noindex or guarantee indexing.

Example

Illustrative example: Disallow: /services/ blocks matching paths unless a more specific Allow rule permits them. Inspect exceptions before changing this or a broad Disallow: / rule.

  1. Open /robots.txt and identify the matching crawler rules.
  2. Find rules covering important pages or required resources.
  3. Edit accidental blocks and verify the published file.
More help and optional notesHigh · Developer
PassRules match the approved crawl policy without accidental important-page or resource blocks.
FailAn applicable rule unintentionally disallows an important URL or needed resource.

If it fails: Correct the accidental rule, preserving intended restrictions.

Retest: Fetch robots.txt and recheck matching paths.

Not applicable: No relevant crawl-policy check.

Keep in mind: Missing robots.txt is not automatically a defect; it does not secure private content.

Optional: useful finding. Keep confidential data out of shared exports.

No result recorded yet.

Changing this result updates your checkmark and progress immediately. Notes are optional.

Set permanent or temporary redirects correctly

Check that moved page addresses reach the right destination.

Use this for: Moved or alternate addresses.

Use a server-side 301 or 308 for a permanent move, and 302 or 307 for a temporary move. A temporary redirect is not automatically an error.

In the CMS redirect manager or server configuration, map the old path to its relevant replacement. Enable Preserve log in Chrome Network, open the old address and inspect Status Code, Location and the final page. Update internal links to the final address to avoid unnecessary hops.

Example

Illustrative example: /old-heating-guide/ permanently moves to /guides/heating/. Add 301 or 308. Without a relevant replacement, use an appropriate missing-page response instead.

  1. Choose permanent or temporary behavior for the real move.
  2. Configure the old-to-new mapping.
  3. Test the chain and update links to the final destination.
More help and optional notesHigh · Developer
PassEach tested move uses the intended behavior and reaches a relevant live destination without a loop.
FailA redirect loops, leads to the wrong page or misrepresents a temporary/permanent move.

If it fails: Correct the type, target or redirect chain.

Retest: Open the old address again.

Not applicable: No moved or alternate addresses.

Keep in mind: Match the real move; avoid irrelevant homepage redirects.

Optional: useful finding. Keep confidential data out of shared exports.

No result recorded yet.

Changing this result updates your checkmark and progress immediately. Notes are optional.

Return a real 404 or 410 for missing pages

Check how your website handles a page that does not exist.

Use this for: Nonexistent and removed pages.

A “page not found” message needs the right HTTP response. Returning 200 with an error message can produce a soft 404: the server claims success without useful content.

Open an invented path and inspect its document in Chrome Network. Ask the developer to return 404, or an appropriate 410 for deliberately removed content, while retaining useful navigation. Repair internal links to removed pages; a correct 404 itself does not need a redirect.

Example

Illustrative example: /this-page-does-not-exist/ shows “Not found” with 200. Make the missing-route handler return 404 while keeping helpful navigation.

  1. Test a path that genuinely does not exist.
  2. Check its response code and useful navigation.
  3. Correct misleading responses and stale internal links.
More help and optional notesMedium · Developer
PassA missing page returns an appropriate 404 or 410 and a useful error experience.
FailMissing pages silently return the homepage or a misleading 200 error response.

If it fails: Correct the missing-route response.

Retest: Request missing and live pages.

Not applicable: No relevant missing-route test.

Optional: useful finding. Keep confidential data out of shared exports.

No result recorded yet.

Changing this result updates your checkmark and progress immediately. Notes are optional.

Control Indexing and Set Canonical URLs

Indexing processes content for possible search inclusion. A crawlable page can intentionally use noindex or duplicate another URL. Inspect these controls before treating “not indexed” as a server fault.

Remove unintended noindex instructions

Find an indexing exclusion and decide whether it belongs on the page.

Use this for: Pages with an intended search status.

Noindex asks a search engine to exclude a page. In Chrome Network, select the document: inspect Headers for X-Robots-Tag and Response for robots or googlebot meta tags. Check Elements too if JavaScript changes the page head.

For an intended search page, turn off accidental “noindex” or “hide from search engines” settings in its SEO controls. Ask the developer to remove unwanted template or header directives. Keep intentional exclusions; private information still needs access control.

Example

Illustrative example: a public service page retains <meta name="robots" content="noindex"> from launch. Remove it, and allow crawling so Google can see the change.

  1. Inspect both meta tags and response headers.
  2. Change the setting responsible for an unintended exclusion.
  3. Reload and confirm the published directive matches your intent.
More help and optional notesHigh · Developer
PassThe directives match the intended indexing policy.
FailAn intended search page has an unintended noindex, or an excluded page lacks its planned control.

If it fails: Remove or correct the unintended directive.

Retest: Recheck headers and HTML.

Not applicable: No applicable public indexing decision.

Keep in mind: Google must be able to crawl noindex.

Optional: useful finding. Keep confidential data out of shared exports.

No result recorded yet.

Changing this result updates your checkmark and progress immediately. Notes are optional.

Choose one canonical URL for duplicate versions

Check that a page points to the intended preferred version.

Use this for: Preferred pages and actual duplicates.

A canonical names the preferred version of duplicate or very similar content. Search the page source for rel="canonical" and compare its target with the intended preferred page. Correct the CMS canonical field or template using the full HTTPS address.

Check tracking copies, alternate hosts and trailing-slash variants. Align internal links and sitemap entries. Redirect duplicates that need not stay accessible. Keep distinct pages separate instead of pointing every service page at the homepage.

Example

Illustrative example: /guides/boiler-care/?campaign=autumn can name the duplicate clean guide as canonical. A distinct boiler-repair service page should keep its own preferred address.

  1. Identify the preferred address and actual duplicates.
  2. Correct the canonical field or template where needed.
  3. Align internal links and sitemap entries with that address.
More help and optional notesHigh · Developer
PassDeclarations match the approved preferred-URL design without contradictory targets.
FailA declaration points to the wrong page or conflicts with the intended mapping.

If it fails: Correct conflicting canonical targets and references.

Retest: Inspect the published declaration.

Not applicable: No relevant canonical mapping.

Keep in mind: Google can choose differently; an absent declaration is not automatically a defect.

More detail (optional)

Canonicals can also use an HTTP Link header. Inspect rendered declarations if JavaScript changes the page head.

Optional: useful finding. Keep confidential data out of shared exports.

No result recorded yet.

Changing this result updates your checkmark and progress immediately. Notes are optional.

Investigate why an important page is not indexed

Separate Google’s indexed record from the page that is live now.

Use this for: Priority URLs in Search Console.

Paste the page address into Search Console URL Inspection. Read Page indexing, the reason and crawl date; use Test live URL to check today’s page.

Fix unintended robots or noindex restrictions. For a different selected canonical, compare the pages and their signals. “Crawled – currently not indexed” alone does not identify a server error; review duplication and usefulness too. After a relevant fix, use Request indexing if available. Repeated requests do not guarantee inclusion.

Example

Illustrative example: Google’s older record shows noindex, but the live page now allows indexing. Verify the change and allow processing time.

  1. Read the indexed reason and crawl date.
  2. Test the live page and correct any unintended restriction.
  3. Recheck later indexing information separately.
More help and optional notesHigh · SEO lead

Before you begin: Correct Search Console property access.

PassThe inspected page’s live crawl and indexing controls match its intended search status, and any reported exclusion has been investigated.
FailA confirmed unintended crawl or indexing restriction remains on the live page.

If it fails: Resolve the identified restriction or canonical conflict.

Retest: Check live and later indexed information.

Not applicable: No relevant inspected URL.

Keep in mind: Being unindexed alone is not a technical failure; live testing cannot predict indexing or canonical selection.

Optional: useful finding. Keep confidential data out of shared exports.

No result recorded yet.

Changing this result updates your checkmark and progress immediately. Notes are optional.

Create, Validate and Submit an XML Sitemap

An XML sitemap lists preferred pages for discovery. Generate it from published content and validate its entries. Submission adds a processing report; a well-linked small site may not need a sitemap project.

Create an automatically updated XML sitemap

Give search engines a maintained list of intended search pages.

Use this for: Sites needing sitemap generation.

Look in your CMS’s SEO or sitemap settings for an existing generated XML sitemap. Use that output rather than maintaining a second competing list. If none exists, enable the built-in sitemap feature or ask the developer to generate one from published pages.

Include full preferred page addresses and arrange for the file to update when pages are published, moved or removed. Open the generated file in a browser to confirm it is publicly accessible.

Example

Illustrative example: publishing /guides/radiator-care/ automatically adds its preferred HTTPS address to the generated sitemap.

  1. Find or enable the CMS sitemap generator.
  2. Select the public page types to include.
  3. Publish the generated file and open it.
More help and optional notesMedium · Developer
PassA public sitemap is generated from the site’s intended published search pages.
FailThe chosen sitemap cannot be generated or opened, or its page source is not maintained.

If it fails: Configure a maintained generator.

Retest: Verify generation in a safe test environment.

Not applicable: Unnecessary sitemap or suitable generator already exists.

Keep in mind: Sitemaps supplement internal links.

Optional: useful finding. Keep confidential data out of shared exports.

No result recorded yet.

Changing this result updates your checkmark and progress immediately. Notes are optional.

Remove broken and excluded URLs from the sitemap

Check that the sitemap lists the pages you want discovered.

Use this for: Existing sitemaps.

Open the generated sitemap and follow entries from your important page types. Check that they resolve to live preferred URLs intended for search. Remove obsolete redirects, missing pages, accidental duplicate variants and pages intentionally excluded with noindex from the generator’s inclusion settings.

If the sitemap includes lastmod, use the date of the page’s meaningful update. Do not refresh every date merely because the sitemap regenerated. Use the generator’s validation output or Search Console’s Sitemaps report to find XML parsing errors after changes.

Example

Illustrative example: replace an obsolete /old-heating-guide/ sitemap entry with its current preferred address in the generator.

  1. Open representative sitemap entries.
  2. Correct inclusion settings and inaccurate dates.
  3. Regenerate and check the resulting file.
More help and optional notesMedium · Developer
PassThe sitemap contains intended canonical search URLs and accurate update values where supplied.
FailIt lists unintended exclusions, broken/obsolete URLs or fabricated lastmod dates.

If it fails: Correct the generation source.

Retest: Open regenerated entries.

Not applicable: No sitemap in use.

Keep in mind: Sitemap inclusion does not guarantee indexing.

Optional: useful finding. Keep confidential data out of shared exports.

No result recorded yet.

Changing this result updates your checkmark and progress immediately. Notes are optional.

Submit your sitemap in Search Console

Tell Google where the sitemap lives and check whether it can be read.

Use this for: Search Console sitemap submissions.

With owner permissions in the correct Search Console property, open Sitemaps. Enter the published sitemap address under Add a new sitemap and choose Submit. You submit its address, not an uploaded copy of the XML.

Open the submitted row and inspect Status. If Google cannot fetch the file, check the address, login restrictions and robots rules. For parsing errors, correct the generator or XML named in the report, then resubmit.

Example

Illustrative example: submitting the live /sitemap.xml produces Success. Google read the file; its listed pages are not thereby confirmed indexed.

  1. Open the correct property’s Sitemaps report.
  2. Submit the public sitemap address.
  3. Investigate any fetch or parsing error.
More help and optional notesMedium · Site owner

Before you begin: Search Console owner permission.

PassThe sitemap is submitted and the report confirms it can be fetched and read.
FailA reported fetch or parsing error remains unresolved.

If it fails: Fix fetch/parsing errors and resubmit.

Retest: Reopen the processed report.

Not applicable: Using another appropriate discovery method.

Keep in mind: Missing permission is a blocker; pending processing is not a confirmed failure.

Optional: useful finding. Keep confidential data out of shared exports.

No result recorded yet.

Changing this result updates your checkmark and progress immediately. Notes are optional.

Make JavaScript, Links and Mobile Content Crawlable

Rendering builds a page from HTML, CSS and JavaScript. Make essential content and links available in that output, including on mobile.

Make JavaScript content available in the rendered page

Check that the built page contains its important text and links.

Use this for: Pages needing rendering checks.

JavaScript can build content after the initial HTML arrives. Compare the document’s Response in Chrome Network with Elements, the browser-built page. Look for essential text and links rather than an empty application container.

For JavaScript-dependent pages, inspect URL Inspection’s live-tested HTML and screenshot when available. Have the developer repair failed script or data requests and unblock required resources. Where appropriate, render important content on the server or during the build so it arrives in the initial HTML.

Example

Illustrative example: service details appear only after “Load details.” Supply essential text without depending on a crawler to press that button.

  1. Compare response HTML with the rendered page.
  2. Inspect Google’s tested output when available.
  3. Fix the failed dependency or content-rendering approach.
More help and optional notesHigh · Developer
PassExpected main content and important links are present in the tested rendered output.
FailThe rendered page is empty, incomplete or depends on unavailable resources.

If it fails: Repair dependencies or interaction-dependent content loading.

Retest: Compare the rendered output again.

Not applicable: No relevant rendering check.

Keep in mind: Your logged-in browser does not prove crawler access.

Optional: useful finding. Keep confidential data out of shared exports.

No result recorded yet.

Changing this result updates your checkmark and progress immediately. Notes are optional.

Use crawlable links to important pages

Check that important navigation is usable and discoverable.

Use this for: Important navigation and contextual links.

Navigation to another page should use an HTML anchor with an href destination. Right-click a menu item in Chrome and choose Inspect. Look for an <a> element with href rather than only a button or div click handler.

In your editor, add relevant descriptive links to important pages reachable only through search or a typed address. Use final preferred destinations. Ask the developer to repair components producing non-link navigation.

Example

Illustrative example: use <a href="/services/boiler-repair/">Boiler repair</a>. A button running only goToService() does not expose the same crawlable destination.

  1. Inspect important menu and contextual links.
  2. Add missing relevant links and correct href destinations.
  3. Follow the published links with mouse and keyboard.
More help and optional notesHigh · Developer
PassImportant destinations use crawlable links that resolve as expected.
FailNavigation relies only on non-link click handlers or malformed destinations.

If it fails: Fix anchors and destinations.

Retest: Inspect and keyboard-test the links.

Not applicable: No navigation links in scope.

Optional: useful finding. Keep confidential data out of shared exports.

No result recorded yet.

Changing this result updates your checkmark and progress immediately. Notes are optional.

Keep important content available on mobile

Check that mobile visitors receive the same important information.

Use this for: Mobile and desktop page versions.

Google uses mobile content for indexing. Compare the same published page on phone and desktop: main text, headings, images, links and structured information should remain equivalent.

In mobile template and visibility settings, restore accidentally omitted sections. Tabs and accordions can work, but essential content must not require a click or swipe to fetch it for the crawler. Inspect the mobile tested output in URL Inspection where available.

Example

Illustrative example: the mobile template omits the service areas listed on desktop. Restore that real information in a readable mobile layout.

  1. Compare the important content on phone and desktop.
  2. Correct mobile-only omissions or indexing settings.
  3. Check the published mobile page and tested output.
More help and optional notesHigh · Developer
PassMobile users and the tested mobile crawler can access equivalent primary content.
FailThe mobile version omits important content or applies unintended different indexing controls.

If it fails: Restore missing mobile content or settings.

Retest: Compare the published versions.

Not applicable: No applicable mobile page comparison.

Optional: useful finding. Keep confidential data out of shared exports.

No result recorded yet.

Changing this result updates your checkmark and progress immediately. Notes are optional.

Improve Page Speed and Core Web Vitals

Core Web Vitals cover loading, interaction and layout stability. Use real-user data where available, then diagnose and fix the responsible resource or code.

Measure real-user LCP, INP and CLS

Use real-user data to check loading, responsiveness and visual stability.

Use this for: Public URL or origin field assessments.

Run the page through PageSpeed Insights and start with the real-user experience section. LCP describes when the largest visible image or text block appears; INP describes interaction responsiveness; CLS describes unexpected visual movement.

Read the assessment for the selected device and confirm whether the data covers This URL or the whole origin. An origin groups the site’s pages and is not a measurement of this page alone. Use the field assessment to choose what needs attention, then diagnose the responsible image, script or moving element. No available field assessment means insufficient data, not an automatic failure.

Example

Illustrative example: mobile origin data fails CLS. Investigate relevant templates; do not assume a newly published article caused the site-wide result.

  1. Run PageSpeed Insights for the page.
  2. Check the field assessment’s scope, device and period.
  3. Identify the metric that needs investigation.
More help and optional notesMedium · Developer
PassPageSpeed Insights reports a passing real-user Core Web Vitals assessment for the stated URL or origin and device.
FailAn available real-user assessment does not pass. If there is no assessment, choose Untested or Blocked rather than Fail.

If it fails: Diagnose the failing metric.

Retest: Review later comparable field data.

Not applicable: Not applicable when the stated scope does not fit.

Keep in mind: No field data means not enough data, not a failing score. Keep this check Untested or Blocked. A laboratory score does not replace real-user evidence.

More detail (optional)

Good field thresholds at the 75th percentile are LCP ≤2.5 seconds, INP ≤200 milliseconds and CLS ≤0.1. PSI can still pass when only INP data is insufficient and LCP/CLS are good; missing LCP or CLS prevents assessment.

Optional: useful finding. Keep confidential data out of shared exports.

No result recorded yet.

Changing this result updates your checkmark and progress immediately. Notes are optional.

Find the resource or interaction slowing the page

Find a repeatable cause of a performance problem.

Use this for: A performance symptom.

In PageSpeed Insights’ diagnostics, open the relevant finding to identify the resource or element. For a slow menu, filter or form, record that action in Chrome DevTools → Performance; a page-load score does not reproduce an interaction.

Repeat tests with comparable device and test conditions. Give the developer the identified image, script, server delay or moving element, then use the matching LCP, INP or CLS task below.

Example

Illustrative example: a filter click freezes while a script rebuilds results. Record that interaction instead of compressing unrelated images.

  1. Open the diagnostic finding or record the slow action.
  2. Identify the resource or code responsible.
  3. Reproduce the symptom before choosing a fix.
More help and optional notesMedium · Developer
PassThe suspected bottleneck can be reproduced and has a scoped fix.
FailA single overall score is reported without an actionable cause or test conditions.

If it fails: Address the reproduced cause.

Retest: Repeat comparable tests and actions.

Not applicable: No performance symptom to investigate.

Keep in mind: Controlled tests do not prove real-user outcomes.

Optional: useful finding. Keep confidential data out of shared exports.

No result recorded yet.

Changing this result updates your checkmark and progress immediately. Notes are optional.

Load the largest visible content sooner

Reduce the delay before the main visible content appears.

Use this for: A diagnosed loading delay.

In PageSpeed Insights or a Chrome Performance recording, identify the LCP element and the part of loading that delays it. If it is an image, provide an appropriately sized compressed file and make its source discoverable early in the HTML. Do not lazy-load an above-the-fold LCP image.

If the delay comes from the server or render-blocking code, ask the developer to address that cause instead. An image-format change alone will not fix a slow server response.

Example

Illustrative example: a carousel script inserts the hero image late. Put its source in initial HTML and remove lazy loading from that visible image.

  1. Find the measured LCP element.
  2. Fix the delay identified for that element.
  3. Repeat comparable loading tests.
More help and optional notesMedium · Developer
PassThe identified loading bottleneck is corrected and comparable tests show an improvement.
FailThe identified delay remains or the change does not improve comparable results.

If it fails: Correct the measured loading bottleneck.

Retest: Repeat loading tests; review later field data.

Not applicable: No LCP bottleneck needs work.

Keep in mind: Local improvement does not establish a passing field assessment.

Optional: useful finding. Keep confidential data out of shared exports.

No result recorded yet.

Changing this result updates your checkmark and progress immediately. Notes are optional.

Reduce JavaScript delays after clicks and taps

Let visitors see a response promptly after interacting.

Use this for: A reproducible interaction delay.

Record the slow click, tap or keyboard action in Chrome DevTools → Performance. Identify whether unrelated work delays the interaction, its handler does too much work, or the browser spends too long updating the layout.

Ask the developer to remove unnecessary handler work, split long JavaScript tasks, and defer nonessential work so the next visual update can happen sooner. Test the whole feature after the change; a fast button that no longer performs its action is not a fix.

Example

Illustrative example: opening a menu also rebuilds recommendations. Show the menu promptly and defer the nonessential recommendation work.

  1. Record the specific delayed interaction.
  2. Reduce or split the identified blocking work.
  3. Retest responsiveness and feature behavior.
More help and optional notesMedium · Developer
PassThe identified interaction delay improves in comparable tests without breaking the action.
FailThe delay persists or the change breaks the intended interaction.

If it fails: Reduce the identified blocking work.

Retest: Record the same interaction again.

Not applicable: No identified interaction bottleneck.

Keep in mind: A page-load score is not INP.

Optional: useful finding. Keep confidential data out of shared exports.

No result recorded yet.

Changing this result updates your checkmark and progress immediately. Notes are optional.

Reserve space for images and late-loading content

Keep page content from unexpectedly jumping as it loads.

Use this for: An identified unexpected shift.

In Chrome DevTools → Performance, inspect a recording of the page loading and being used. Locate the layout shift and the content that appeared above or beside it.

Give images correct width and height attributes or an appropriate CSS aspect-ratio. Reserve space for embeds or banners before they arrive. If a late font or injected component moves the text, have the developer adjust that component’s sizing or loading behavior. Test narrow screens as well as desktop.

Example

Illustrative example: a late testimonial widget pushes the contact form down. Reserve its space or reposition it to avoid displacing visible content.

  1. Find the element and event causing the shift.
  2. Add appropriate dimensions or reserved space.
  3. Retest loading and later interactions.
More help and optional notesMedium · Developer
PassThe identified shift is prevented or reduced without clipping useful content.
FailThe same unwanted shift remains or the sizing fix hides content.

If it fails: Reserve space or correct dimensions.

Retest: Repeat loading and later interactions.

Not applicable: No layout-shift problem needs work.

Keep in mind: Later shifts may escape short loading tests.

Optional: useful finding. Keep confidential data out of shared exports.

No result recorded yet.

Changing this result updates your checkmark and progress immediately. Notes are optional.

Use HTTPS and Validate Structured Data

Check HTTPS certificates and resources, keep structured data truthful, and verify public output after changes.

Fix HTTPS and mixed-content problems

Check that your preferred secure website address works correctly.

Use this for: Preferred host and intended variants.

Open your preferred HTTPS homepage and important pages. Stop at browser security warnings; ask the host to repair an expired or mismatched certificate.

In Chrome DevTools → More tools → Privacy and security, inspect Security for non-secure origins. Replace HTTP image, script or stylesheet references with working HTTPS versions. Check that HTTP alternatives reach the intended HTTPS page and canonical links use the secure address.

Example

Illustrative example: an HTTPS page loads its banner over HTTP. Update the template’s image source to its working HTTPS address.

  1. Check HTTPS pages without bypassing warnings.
  2. Inspect the Security section for the affected origin.
  3. Fix certificate or resource references and retest.
More help and optional notesHigh · Developer
PassThe preferred HTTPS route works without certificate or mixed-content problems.
FailA certificate failure, insecure dependency or HTTPS-to-HTTP redirect undermines the intended route.

If it fails: Repair certificates, insecure resources or routing.

Retest: Recheck the affected secure page.

Not applicable: No website connection in scope.

Keep in mind: Never bypass a browser security warning.

Optional: useful finding. Keep confidential data out of shared exports.

No result recorded yet.

Changing this result updates your checkmark and progress immediately. Notes are optional.

Correct structured data to match the visible page

Check that machine-readable page information matches visible facts.

Use this for: Relevant implemented structured data.

Structured data describes page facts in machine-readable form, often JSON-LD. Find the CMS schema setting or producing template, then compare its properties with visible content.

Use Schema Markup Validator for vocabulary checks and Google’s Rich Results Test for supported Google features. Fix relevant errors and remove unsupported ratings, reviews or other invented properties. When adding markup, follow the current requirements for the real page type; optional fields do not justify inventing facts.

Example

Illustrative example: product schema shows outdated availability. Generate it from the same real product data as the visible page.

  1. Identify the implemented type and its source setting.
  2. Compare its properties with visible facts.
  3. Correct inaccuracies and rerun the relevant validator.
More help and optional notesMedium · Developer
PassThe markup matches visible facts and satisfies requirements for the chosen applicable type.
FailIt invents reviews, entities or attributes, or has errors affecting the intended feature.

If it fails: Fix unsupported facts and applicable errors.

Retest: Validate published markup again.

Not applicable: No relevant schema implementation.

Keep in mind: Valid schema does not guarantee rich results; not every type has a Google feature.

Optional: useful finding. Keep confidential data out of shared exports.

No result recorded yet.

Changing this result updates your checkmark and progress immediately. Notes are optional.

Check the published page after a technical fix

Check the actual published result after a technical fix.

Use this for: Published technical corrections.

After publication, repeat the original test on the public URL. Inspect what visitors receive, not just the editor. If old output remains, have the developer check deployment and the relevant cache.

For a shared-template change, inspect another page using it. You can verify the live fix immediately even while Google’s indexed record reflects an older crawl.

Example

Illustrative example: the editor removes noindex, but X-Robots-Tag: noindex remains in the response. Correct that server-header rule too.

  1. Repeat the original test on the public URL.
  2. Check another affected template example.
  3. Resolve stale output or remaining conflicts.
More help and optional notesHigh · Developer
PassThe original defect is resolved without a new conflicting output.
FailOnly the CMS or code change was inspected, or cached production output still has the defect.

If it fails: Resolve stale output or remaining conflicts.

Retest: Repeat the original failing test.

Not applicable: No technical fix to verify.

Keep in mind: Google’s record can update after the live fix.

Optional: useful finding. Keep confidential data out of shared exports.

No result recorded yet.

Changing this result updates your checkmark and progress immediately. Notes are optional.

Reset this checklist?

This removes saved statuses, evidence and result dates for the checks on this page. Other checklists keep their records. Export a CSV first if you need a copy.

Quick reference

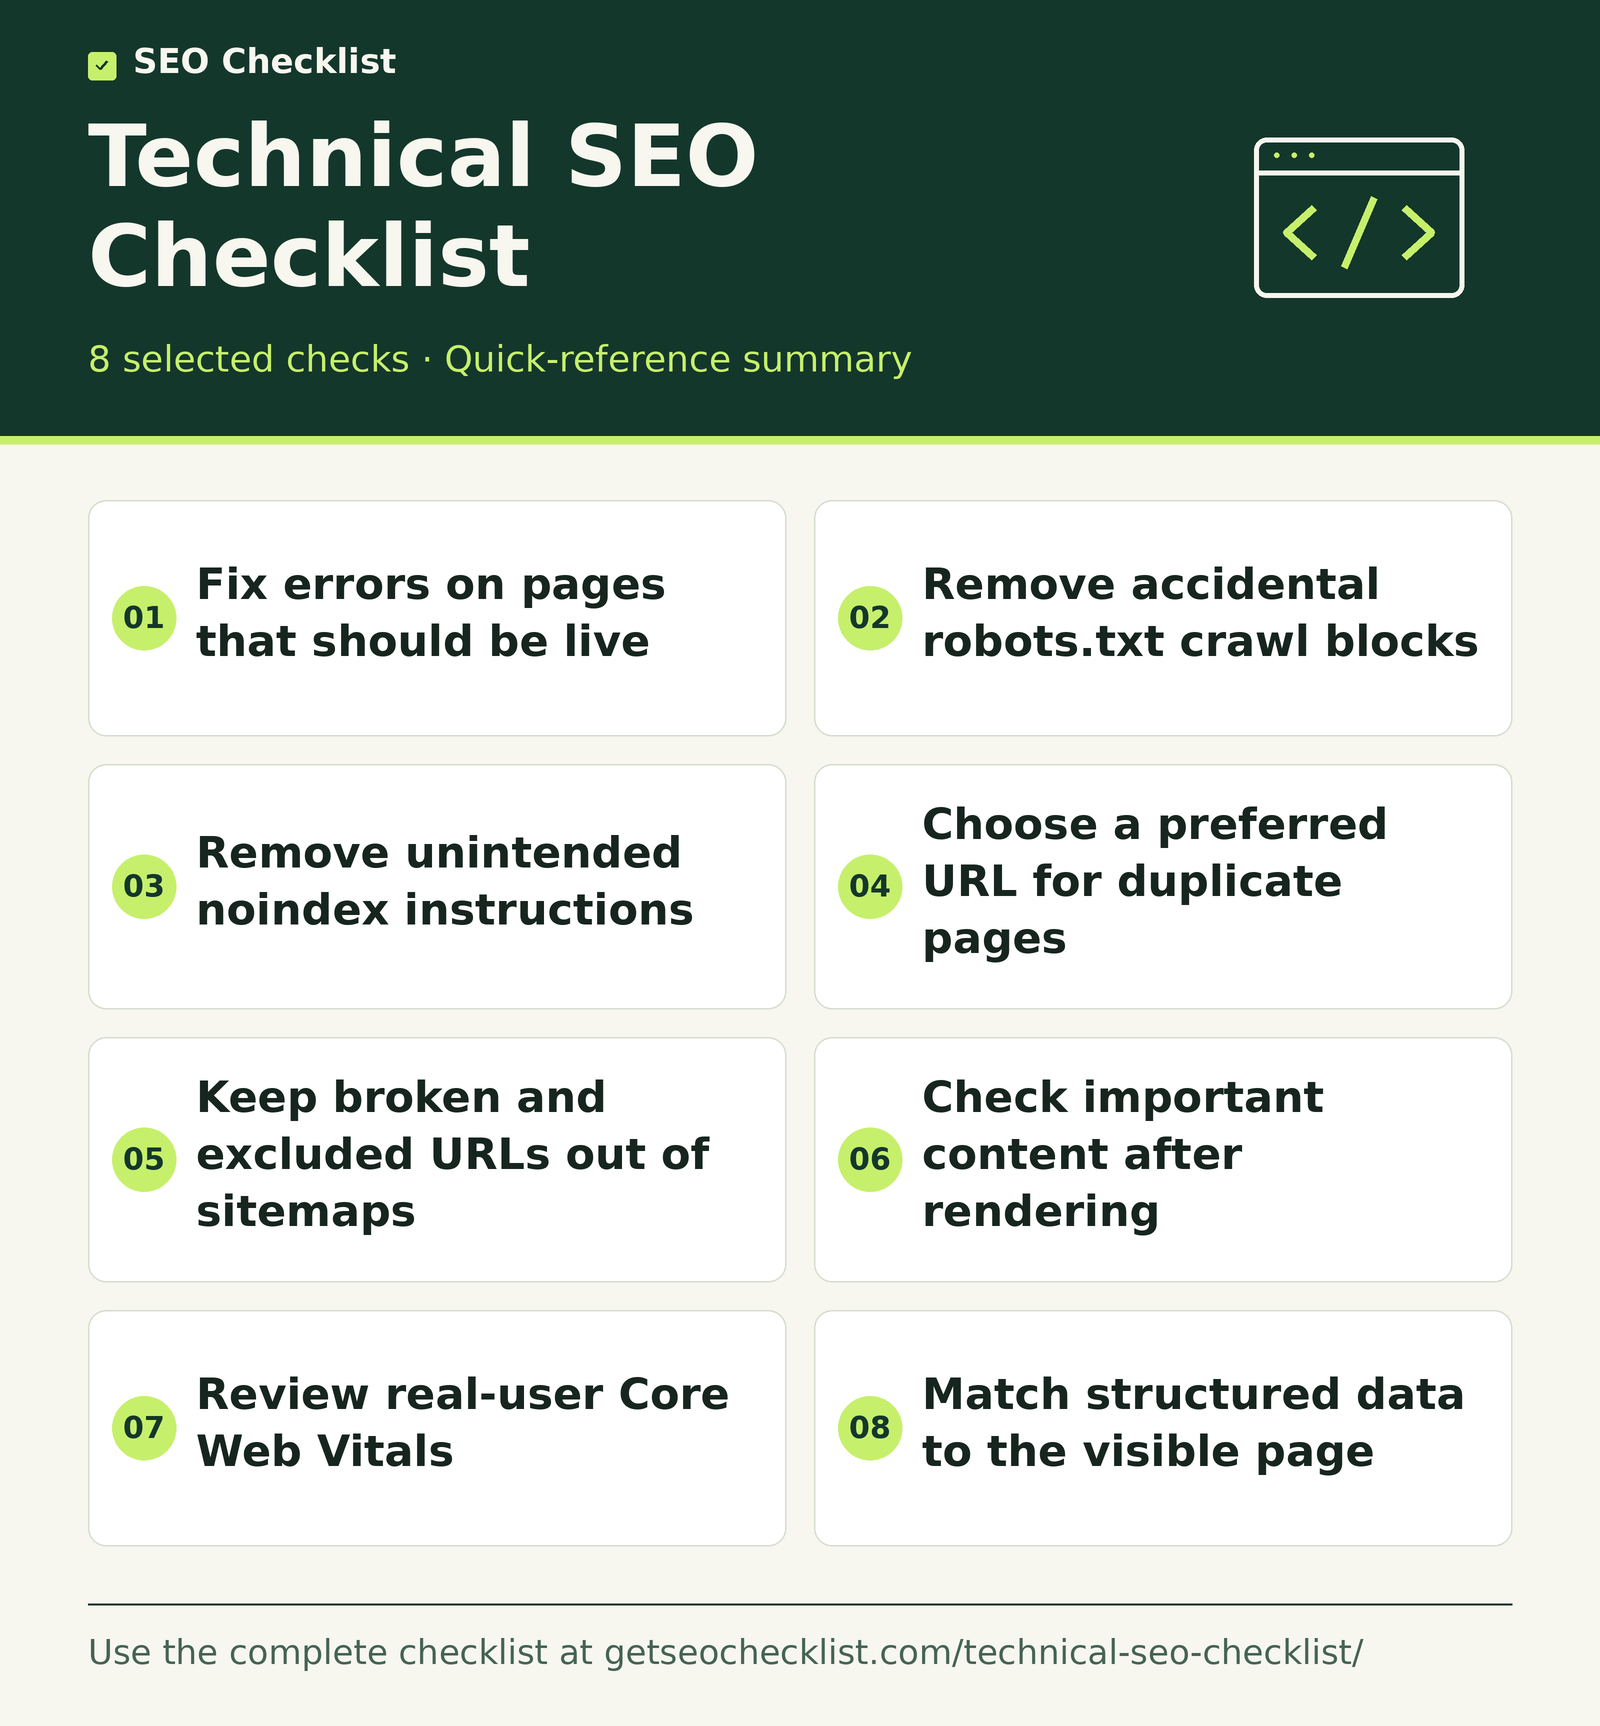
Technical SEO Checklist infographic

Keep these eight selected actions handy. The complete checklist above includes the steps, conditions and follow-up checks.

Technical SEO Checklist infographic summarizing HTTP errors, crawling, indexing, canonicals, sitemaps and page experience. Text version below.
Eight selected actions from Technical SEO Checklist. Use the complete checklist for steps, conditions and retests.
Read the infographic as text
  1. Fix errors on pages that should be live
  2. Remove accidental robots.txt crawl blocks
  3. Remove unintended noindex instructions
  4. Choose a preferred URL for duplicate pages
  5. Keep broken and excluded URLs out of sitemaps
  6. Check important content after rendering
  7. Review real-user Core Web Vitals
  8. Match structured data to the visible page

Choose an action to open its full instructions above.

A useful result, every time

Check a task. Choose a result.

This is a manual SEO workflow. It helps you decide what to investigate and keep a usable record. It does not crawl your website or verify your answers automatically.

  1. Choose your scope. Pick the relevant task group and representative pages you are authorized to inspect.
  2. Run the stated check. Follow the steps, then choose your result. Click the square for Pass, or use the result menu for another status. You do not need to type anything.
  3. Assign the next action. Fix a problem when you can, or ask the right person for help. Optional notes can remind you what to do next. Check the result again after a fix.

What your progress means

Review progress counts passes and failures against applicable checks. Failed work still counts as reviewed. Blocked and untested checks remain unfinished. This is not an SEO score.

Untested
You have not checked this yet.
Pass
You checked it and it works as described.
Fail
You checked it and found something to fix.
Blocked
You need access, information or someone’s help.
Not applicable
This task does not apply to your website.

Export CSV downloads the checks currently shown and any optional notes. Print expands the instructions for that view. Saved results stay in this browser; there is no account sync.

A visual working guide

Test each technical condition independently

Four distinct technical checks: URL discovery, fetching, rendering, and indexing signals. Passing a check does not guarantee indexing.
The diagram organizes separate checks; it is not proof that a search engine follows one fixed path or will index a page. Original instructional illustration.
Apply the workflow

Technical SEO Checks for the Features Your Site Uses

Apply the core tasks to public pages. Add filter, pagination or language checks only for features you use; preserve intentional exclusions.

Start a Technical SEO Audit with Your Important Pages

Start with the homepage and important service, product, guide or contact templates. If you find a shared-template problem, inspect another page using it.

If a live page will not load, check HTTP first. If it is missing from search, inspect crawl, noindex and canonical settings. If it feels slow, distinguish loading, interaction and layout movement. Follow the instructions before choosing a result; leave unchecked tasks untested and inaccessible work blocked. Notes remain optional.

Fix Technical SEO Problems in Templates and Server Settings

Ask for the specific change at its source: “Remove the unintended noindex header from public service pages while retaining it on the thank-you page.” A page setting cannot override a conflicting server header.

For broad template changes, use a safe test environment before publication. Then inspect the public response and test important navigation and forms.

Handle Filters, Pagination and Language Versions When They Exist

Use these checks only when the feature exists.

Filters: inspect generated parameter URLs. Keep useful search landing pages and have the developer control unnecessary combinations. Do not block crawling while relying on Google to read noindex on the blocked page.

Pagination: give later results distinct URLs, such as /guides/?page=2, and crawlable links. Genuinely different results pages need their own canonical; a Load more button should not be the only discovery route.

Languages: annotate real equivalent versions with hreflang using supported language and optional region codes. Include each page itself and reciprocal references. Real English and French equivalents can use en and fr; do not invent regional pages to fill annotations.

Correct a Canonical That Points to the Wrong Page

Imagine a distinct boiler-care guide declaring the homepage canonical because of a reused template default. Set the guide’s own full preferred address in its canonical field or template. Inspect published output and check related guides for the same mistake.

Align conflicting internal links and sitemap entries. Later compare Google’s selected canonical in URL Inspection; a live test cannot establish that its index has already changed.

Which focused checklist should you use for a crawl or indexing issue?

Choose the specialist workflow that matches the question you need to answer. Crawling a page and deciding whether it is eligible for indexing are different checks; a successful result in either does not guarantee a search listing.

Check Mobile Experience, Secure Delivery and Structured Data

After verifying access and indexing signals, use a focused workflow for the template or delivery problem you found. Mobile parity, field performance, resource optimization, HTTPS and structured data each need different evidence.

Continue With a Focused Technical Review

Use the workflow that matches the discovery, rendering or delivery issue you are investigating.

A clear process, with honest limits.

Follow the steps, choose the result that matches what you found, and check again after changes. Notes are optional. A completed check does not guarantee indexing, traffic or rankings. How the checklists work.